OpenRouter’s New Top 20 Is a Preview of a Post-Chatbot Model Market

The most revealing thing about this week’s model rankings is that three products can compete on the same chart while barely competing for the same job. An anonymous multimodal preview, Xiaomi’s throughput-focused model, and a typed decision engine collectively generated nearly 6.6 trillion tokens in a week. Calling that a chatbot race misses the engineering story: developers are beginning to buy model behavior the way they buy infrastructure—by workload, contract, latency, and risk.
OpenRouter’s latest top 20 makes that split unusually visible. Space Bunny Alpha entered at number 11 with 2.94 trillion tokens after roughly two days of availability. Jev 1.13 jumped six places to number 14, growing more than 999% to 1.85 trillion tokens. Xiaomi’s new MiMo-V2.6-Flash arrived immediately behind it at number 15 with 1.83 trillion tokens.
Those are usage rankings, not quality scores. OpenRouter counts tokens processed; it does not rank unique users, request volume, customer spend, successful tasks, or benchmark accuracy. A free preview with long reasoning traces can climb faster than a concise paid model that handles more requests. Still, 6.6 trillion tokens is not a rounding error. It is evidence that developers are testing three distinct operating models at production-like scale.
Space Bunny is a subsidized evaluation campaign
Space Bunny Alpha is the loudest arrival because it combines mystery with an unusually generous interface. OpenRouter lists text, image, and video input, adjustable reasoning, tool use, a one-million-token context window, and a maximum completion length of 524,288 tokens. It is also free during preview. The internet has naturally focused on guessing the lab behind it, including unsupported theories about MiniMax and Kimi ancestry. That is entertaining and operationally irrelevant.
The useful interpretation is that the anonymous provider is buying evaluation data with compute. Its terms allow prompts and completions to be logged for training or evaluation. For public repositories, synthetic workloads, and disposable benchmarks, that can be a rational trade. For proprietary code, customer records, credentials, incident logs, or an unreleased roadmap, it is a hard stop.
Engineers should treat the free endpoint as a public test environment rather than a bargain production tier. Create a sanitized task suite, pin the exact model identifier, and measure time to first token, tool-call validity, retries, end-to-end task completion, and variance across repeated runs. A million-token context window is only useful if retrieval remains reliable deep into the prompt; a half-million-token output ceiling is a capability boundary, not a design target. Letting an agent discover that boundary in production is less a benchmark than an incident report waiting to happen.
There is also lifecycle risk. OpenRouter’s earlier anonymous animal previews were eventually connected to named labs, and free windows have often closed quickly. A model alias can change, a price can appear, or behavior can shift at reveal. The right architecture keeps this experiment behind a provider-neutral interface with cost limits, data classification, and a tested fallback. Free compute is temporary; coupling tends to be permanent.
MiMo’s real contest may be with MiMo
Xiaomi released MiMo-V2.6 on September 22 in Pro, Flash, and Pro Ultraspeed variants. The company positions Flash for low-cost, high-frequency use and says Ultraspeed preserves Pro-level capability at up to 20 times the speed. MiMo-V2.6-Flash’s immediate 1.83-trillion-token debut looks impressive, but the adjacent movement matters more: MiMo-V2.5 fell from sixth to seventh as weekly use contracted 35%, even while retaining 4.93 trillion tokens.
That pattern suggests migration within Xiaomi’s own family, not simply 1.83 trillion tokens of new demand. Product teams often mistake a new model’s launch traffic for market expansion when users are actually shifting workloads from the predecessor. The distinction matters for capacity planning and vendor evaluation. A provider that can move customers to a better price-performance point without breaking their applications has a strong platform story; a provider merely splitting usage among overlapping SKUs has created a naming problem.
MiMo should therefore be tested on the high-volume lane, where small differences compound: classification, extraction, code transformation, image understanding, and repetitive agent steps. Replay real traces rather than relying on a vendor benchmark average. Record output tokens per successful task, not just price per million tokens. A cheap model that needs three retries, emits bloated reasoning, or fails schemas can cost more than the expensive one it replaces.
Jev turns uncertainty into an API contract
Jev is the genuinely different entrant. It is not a conventional generative model and does not sell better prose. Given up to 32,000 input tokens, Jev returns one of three typed primitives: Choice, Score, or Noul, its yes-or-no probability type. OpenRouter’s documentation shows a billing ticket routed to a fixed label with the full probability distribution returned, rather than an LLM being politely asked to produce valid JSON.
The economics are equally narrow: $0.042 per million input tokens, with output free. A documented routing example using 357 input tokens cost $0.000014994. At number 14 with 1.85 trillion weekly tokens, Jev’s rise says there is substantial demand for decisions that are cheap, constrained, and measurable rather than fluent.
This is more important than another leaderboard shuffle. Many production “LLM tasks” are not language generation at all. They are gates: Is this transaction suspicious? Which queue owns this support request? Should this agent be allowed to execute a tool? Does this response require human review? General models can answer those questions, but their natural interface—unbounded text—forces developers to add parsers, retries, and confidence heuristics after the fact. Jev makes the output space and uncertainty part of the contract.
That does not make a returned probability automatically trustworthy. Calibration is measured across a labeled population, not inferred from one confident-looking number. Teams evaluating Jev should build a holdout set that reflects their actual traffic, plot reliability by probability bucket, and select thresholds using the real costs of false positives and false negatives. Send the ambiguous band to a human or a stronger model. A useful decision system is often three-way—approve, reject, escalate—even when the business question pretends to be binary.
The leaderboard is becoming a scheduler
The top five did not reorder, but their trajectories reinforce the same point. GLM 5.3 Flash grew 67% to 19 trillion weekly tokens and DeepSeek V4.1 Flash grew 60% to 18.9 trillion. Meanwhile GPT-5.6 Luna contracted 45% to 8.7 trillion and DeepSeek V4 Flash 0731 fell 22% to 8.3 trillion. Distribution and economics can reorganize usage much faster than benchmark Elo moves.
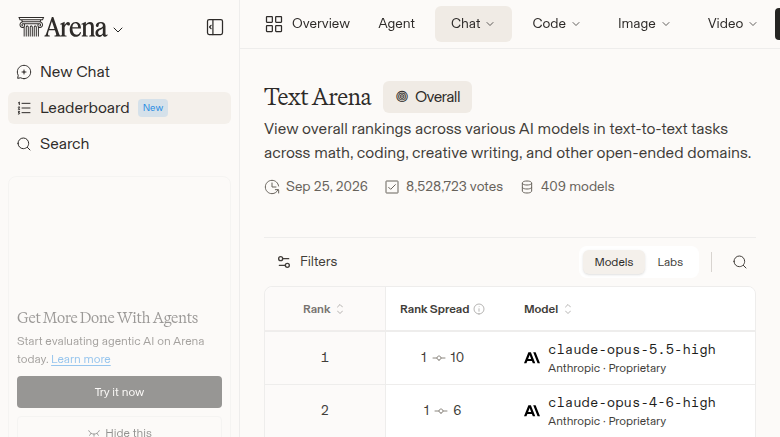
Arena’s text leaderboard, in contrast, remains unchanged on its September 13 dataset. Anthropic holds seven of its top 20 positions, including the top three, while Meta and Google also occupy multiple high-ranking slots. That is useful evidence about human preference under Arena’s methodology, but it answers a different question. Arena asks which outputs evaluators prefer; OpenRouter reveals where developers are spending tokens. Neither tells you which system will complete your workload most reliably per dollar.
The practical response is not to crown a new winner every morning. Build a small internal routing benchmark with four columns that public leaderboards routinely blur: success rate, tail latency, total cost per successful task, and data-handling constraints. Separate generation, perception, and decisions into distinct lanes. Keep a stable baseline in each lane, evaluate challengers with replayed traces, and require a meaningful margin before switching. Also monitor model IDs and provider terms as carefully as accuracy; a silent alias change can invalidate yesterday’s evaluation.
The model market is starting to look less like a single league table and more like a scheduler choosing specialized workers. Space Bunny offers subsidized multimodal experimentation. MiMo-V2.6-Flash competes on efficient throughput. Jev offers typed uncertainty for gates and routers. The winners will not be the teams that guess which model is universally smartest. They will be the teams that know which job requires generation, which requires perception, which requires a calibrated decision—and refuse to pay a flagship chatbot to do all three.
Sources: OpenRouter rankings, Space Bunny Alpha model page, Xiaomi MiMo release notes, OpenRouter’s Jev explainer, Jev documentation, Arena AI leaderboard