The  LGTM
  • Home
  • Agentic Coding
  • Claude Code
  • Codex
Sign in Subscribe
Production Agents Do Not Need Better Demos. They Need Fresh Data, Safe Writes, and Receipts.
ai-frameworks

Production Agents Do Not Need Better Demos. They Need Fresh Data, Safe Writes, and Receipts.

A lot of agent postmortems are going to look embarrassingly familiar once teams stop blaming the model. The agent reordered inventory from stale stock data. It closed an incident because one system said resolved while the rollback was still pending somewhere else. It issued a refund against a customer record
26 May 2026 4 min read
Qwen Code’s May 26 Nightly Hardens the Local Agent Runtime
agentic-coding

Qwen Code’s May 26 Nightly Hardens the Local Agent Runtime

Qwen Code’s May 26 nightly is the kind of release that does not win launch-day screenshots and absolutely matters if you run coding agents for real work. The headline is not a new model, a prettier terminal, or a benchmark victory lap. It is runtime hardening: budgets, concurrency, telemetry,
26 May 2026 5 min read
Coding Agents Do Not Need More Speed. They Need a Verification Loop
agentic-coding

Coding Agents Do Not Need More Speed. They Need a Verification Loop

The uncomfortable truth about AI coding agents is that speed stopped being the impressive part. The demos already proved they can generate code faster than a human can review it. The unresolved question is whether a team can merge that code without turning software delivery into a trust fall with
26 May 2026 4 min read
Claw-Anything Shows Always-On Assistants Are Failing the Context Test
ai-models

Claw-Anything Shows Always-On Assistants Are Failing the Context Test

Always-on assistants keep failing the same quiet test: they are useful only if they understand context you did not paste into the chat box. Claw-Anything, a new benchmark from LiberCoders, is valuable because it makes that failure measurable. It gives agents a simulated user world with long-horizon activity, interconnected services,
26 May 2026 5 min read
WBench Is a Better World-Model Gut Check Than Another Pretty Video Leaderboard
ai-models

WBench Is a Better World-Model Gut Check Than Another Pretty Video Leaderboard

Video generation has had a beauty-contest problem for years: show the best five seconds, crop out the failure, call it a world model. WBench, a new benchmark from Meituan LongCat, is useful because it asks a less flattering question: can the model preserve a world after the user starts interacting
26 May 2026 4 min read
Macaron-A2UI Says the Next Agent UI Is Not Another Chat Bubble
ai-models

Macaron-A2UI Says the Next Agent UI Is Not Another Chat Bubble

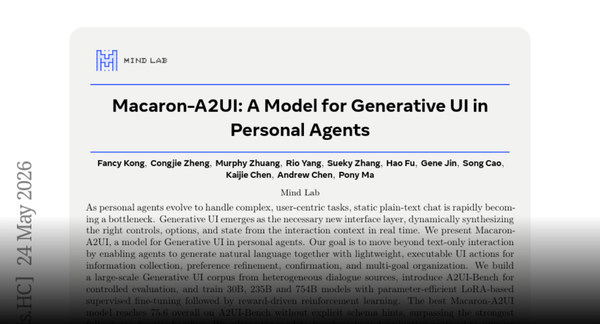
The next useful agent interface is probably not another blank chat box with better placeholder text. Macaron-A2UI, a new generative-UI model family from Mind Lab surfaced through Hugging Face Papers, is interesting because it treats interface generation as a model-output problem with an actual contract: the assistant can respond in
26 May 2026 4 min read
codex

Codex Fixes macOS stderr Corruption Without Blinding Developers to Diagnostics

A terminal UI bug in Codex sounds like small potatoes until you have watched diagnostic text paint over the prompt where a developer is trying to steer an agent. Then it stops being cosmetic. It becomes a trust problem: did the tool corrupt my input, lose my command, leak something
26 May 2026 4 min read
codex

Codex Tightens the Trust Boundary Between TUI Config, MCP Inventory, and Automated Hooks

The most important Codex changes on May 25 were about authority: who owns MCP state, who persists trust decisions, and when a dangerous automation flag should actually bypass a hook review. That sounds like terminal UI plumbing until you remember what Codex is becoming. A coding agent with remotes, app
26 May 2026 4 min read
codex

Codex’s May 25 Runtime Work Is About State, Not Sparkles: Doctor Audits, Remote Status, and Rate-Limit Semantics

Codex’s most useful work on May 25 was not a new model, a shinier autocomplete demo, or another screenshot-friendly agent trick. It was a set of runtime-observability changes that answer the question every platform team eventually asks after deploying a coding agent: when the local files, app server, remote
26 May 2026 4 min read
Detectify’s MCP Server Is the AppSec Version of Letting the Agent Run the Test
claude-code

Detectify’s MCP Server Is the AppSec Version of Letting the Agent Run the Test

Detectify’s new MCP Server is easy to file under “security vendor ships integration.” That would miss the point. The more interesting story is that application security is being forced into the agent loop, because the old workflow — scanner finds bug, dashboard waits, human reads report, ticket appears, developer eventually
26 May 2026 5 min read
OpenClaw’s ENETDOWN Crash Is a Reminder That SSRF Guards Are Still Network Code
openclaw

OpenClaw’s ENETDOWN Crash Is a Reminder That SSRF Guards Are Still Network Code

Security code does not get a pass on being production code. OpenClaw issue #86688 is a clean reminder: an SSRF guard that crashes the gateway when the network drops has moved the risk, not removed it. The report says OpenClaw’s gateway can exit on an uncaught ENETDOWN error while
25 May 2026 4 min read
openclaw

A sessions_yield Compaction Bug Shows Why Multi-Agent State Needs Branch Discipline

The dangerous bugs in multi-agent systems are rarely the theatrical ones. They are the quiet state bugs: the parent session parks, the subagent finishes, the runtime wakes the parent, and somewhere in that handoff an internal marker starts acting like the real conversation. That is the shape of OpenClaw issue
25 May 2026 4 min read
← Newer Posts Page 77 of 141 Older Posts →
The LGTM © 2026
  • Sign up
Powered by Ghost