The  LGTM
  • Home
  • Agentic Coding
  • Claude Code
  • Codex
Sign in Subscribe
The Models Developers Pay to Run Are Not the Models They Prefer
llm-rankings

The Models Developers Pay to Run Are Not the Models They Prefer

The most important model ranking this week is not a ranking of intelligence. It is a bill. OpenRouter’s latest usage table shows developers sending 9.95 trillion weekly tokens through Xiaomi’s MiMo-V2.5, 5.81 trillion through DeepSeek V4 Flash, and a combined 7.70 trillion through Tencent’
26 Jul 2026 5 min read
The Model Market Is Splitting: Open Weights Own Volume While GPT-5.6 Buys Speed
llm-rankings

The Model Market Is Splitting: Open Weights Own Volume While GPT-5.6 Buys Speed

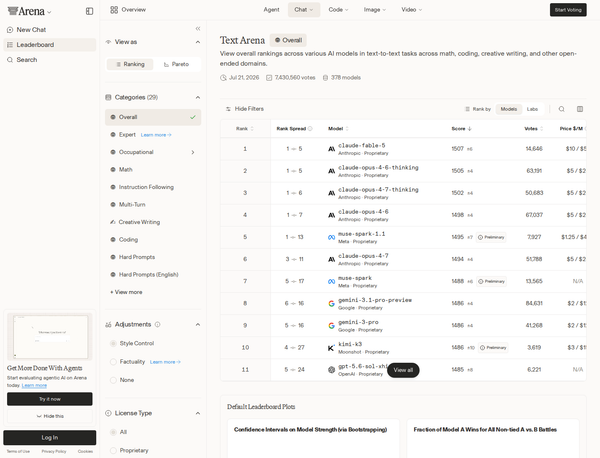
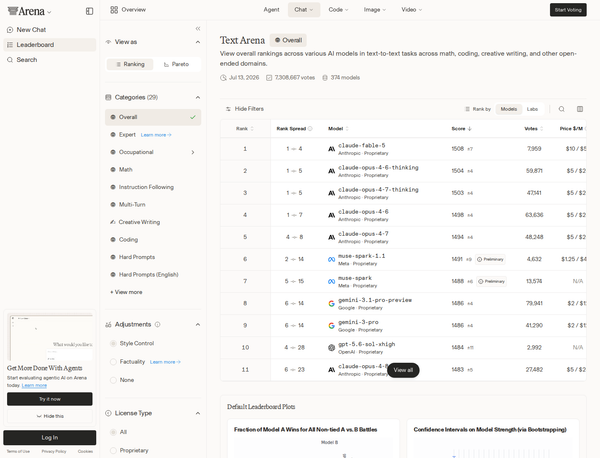
The most useful model leaderboard this week is the one that refuses to crown a winner. Arena AI’s preference board did not move at all: Anthropic still holds six of the first seven positions, led by Claude Fable 5 at 1507 Elo, with Claude Opus 4.6 Thinking two
25 Jul 2026 5 min read
The Model People Prefer Is Not the Model Builders Actually Run
llm-rankings

The Model People Prefer Is Not the Model Builders Actually Run

The most important model leaderboard result this week is not that Xiaomi moved into first place. It is that the model most heavily used through OpenRouter is nowhere near the models people most often prefer in Arena AI’s blind comparisons. That gap is no statistical footnote. It is the
24 Jul 2026 5 min read
Meta Cracks the Claude Wall in Arena, While Usage Still Chases Cheap Tokens
llm-rankings

Meta Cracks the Claude Wall in Arena, While Usage Still Chases Cheap Tokens

The most useful leaderboard story today is not that Anthropic is losing. It is not. Claude still owns the top of Arena AI's text leaderboard so thoroughly that the first four slots read like an internal product lineup: Claude Fable 5, Claude Opus 4.6 Thinking, Claude Opus
22 Jul 2026 5 min read
Kimi K3 Shows Why LLM Rankings Are Splitting Into Two Markets
llm-rankings

Kimi K3 Shows Why LLM Rankings Are Splitting Into Two Markets

The most interesting thing in this week's LLM rankings is not that another model moved into the top 10. That happens often enough now that it barely qualifies as news. The interesting part is that the model doing it, Moonshot's Kimi K3, looks more impressive on
18 Jul 2026 6 min read
LLM Rankings Have Split Into Prestige Models and Workhorse Models
llm-rankings

LLM Rankings Have Split Into Prestige Models and Workhorse Models

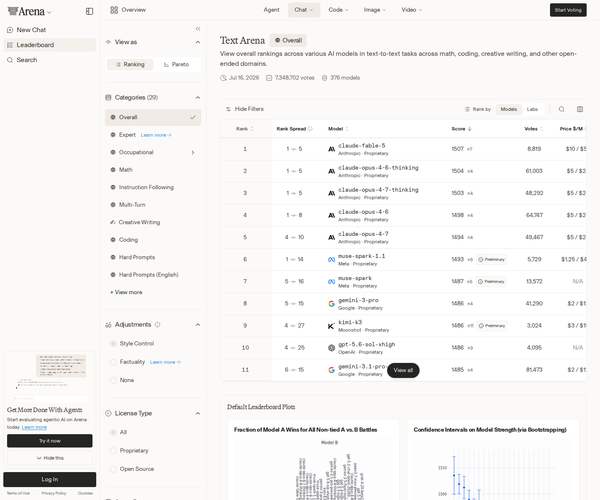
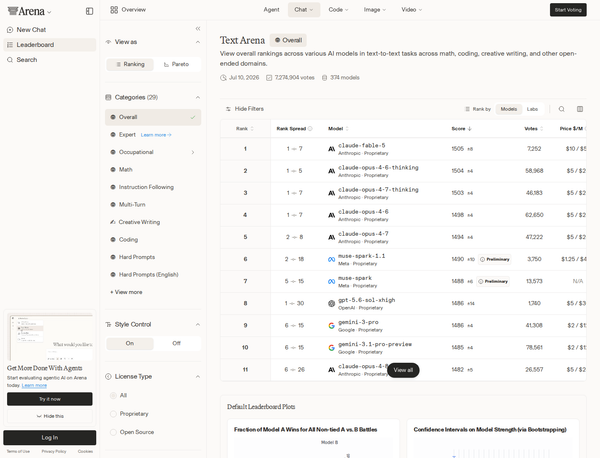
The most useful LLM ranking this week is not the one with the cleanest number one. It is the gap between the rankings. Arena's Text leaderboard still looks like a prestige table: Anthropic occupies the entire top five, with claude-fable-5 at 1508 Elo, claude-opus-4-6-thinking at 1504, claude-opus-4-7-thinking at
16 Jul 2026 6 min read
LLM Rankings Are Splitting Into Prestige Models and Workhorse Models
llm-rankings

LLM Rankings Are Splitting Into Prestige Models and Workhorse Models

The most useful LLM ranking this week is not the one where the “best” model changed. It is the one where the most-used model changed. OpenRouter’s weekly rankings now have MiMo-V2.5 at number one with 5.40 trillion tokens routed over the last week, just ahead of DeepSeek
13 Jul 2026 6 min read
LLM Rankings Have Split Into Prestige Models and Workhorse Models
llm-rankings

LLM Rankings Have Split Into Prestige Models and Workhorse Models

The useful question in LLM rankings is no longer “which model is best?” That question was always too vague, but now it is actively misleading. The leaderboard world has split into two markets: models that win judged preference tests, and models that developers route trillions of tokens through because they
12 Jul 2026 6 min read
Tencent's Hy3 Shows the Free-Tier Leaderboard Effect Is Real
llm-rankings

Tencent's Hy3 Shows the Free-Tier Leaderboard Effect Is Real

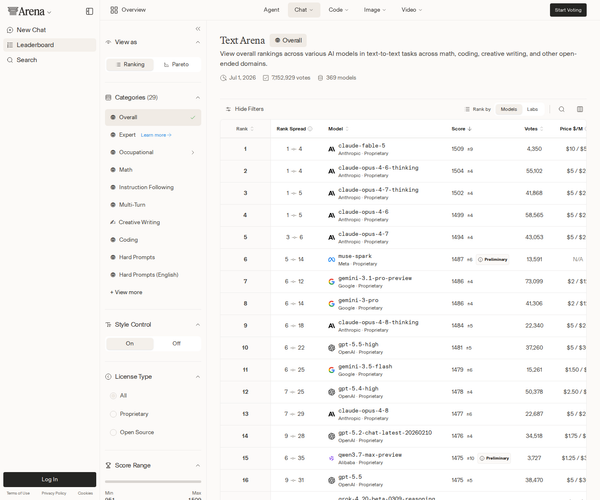
The interesting LLM ranking this week is not on the board everyone argues about. Arena AI's text leaderboard was basically frozen: Anthropic still owns the top cluster, Google and OpenAI are still bunched close behind, and nobody broke into the top 20. The real movement came from OpenRouter,
10 Jul 2026 5 min read
LLM Rankings Have Forked Into Prestige and Production
llm-rankings

LLM Rankings Have Forked Into Prestige and Production

Leaderboards are usually treated like scoreboards. That is the first mistake. This week's LLM rankings are better read as a market map: one board shows which models win judged preference, while another shows which models developers actually route when money, latency, quotas, defaults, and reliability enter the room.
08 Jul 2026 5 min read
llm-rankings

LLM Rankings Are Splitting Quality Signals From Production Demand

The useful thing about today's LLM rankings is how little the top of the charts moved. That sounds like a boring leaderboard day, but it is the opposite. When the prestige rankings freeze and the usage rankings keep shifting underneath them, you get a cleaner view of the
06 Jul 2026 6 min read
LLM Rankings Have Split Into Prestige Models and Production Workhorses
llm-rankings

LLM Rankings Have Split Into Prestige Models and Production Workhorses

The useful LLM leaderboard story this week is not that one model moved one slot. That is leaderboard cosplay. The real story is that the industry now has two different scoreboards telling two different truths: models that win judged preference tests, and models that developers are willing to route trillions
05 Jul 2026 6 min read
← Newer Posts Page 6 of 141 Older Posts →
The LGTM © 2026
  • Sign up
Powered by Ghost