The  LGTM
  • Home
  • Agentic Coding
  • Claude Code
  • Codex
Sign in Subscribe
The LLM Leaderboard Has Forked Into Quality and Throughput
llm-rankings

The LLM Leaderboard Has Forked Into Quality and Throughput

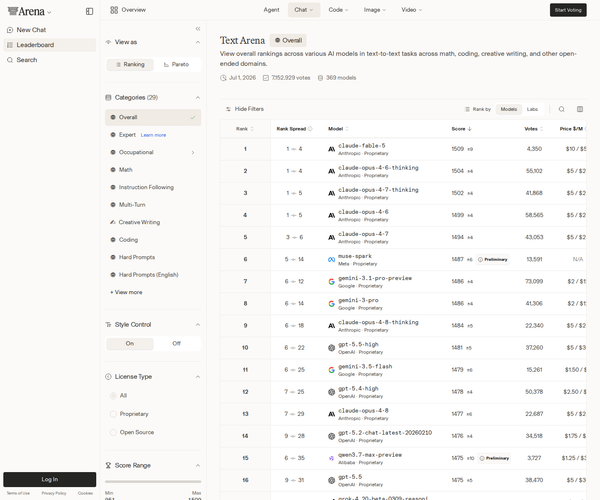
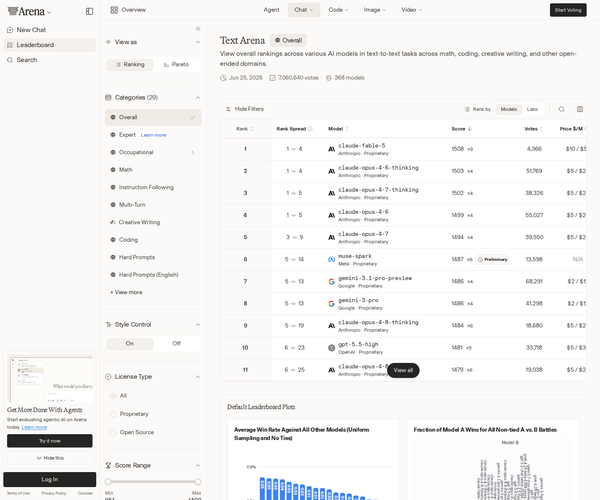
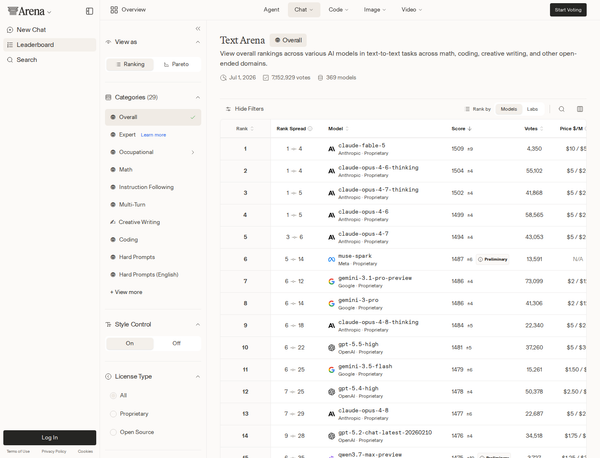
The most useful thing in this week's LLM rankings is not the model sitting at #1. It is the disagreement between the boards. On Arena Text, Anthropic still owns the top of the judged-quality stack: claude-fable-5 leads at 1509 Elo, followed by claude-opus-4-6-thinking at 1504, claude-opus-4-7-thinking at 1502,
04 Jul 2026 5 min read
LLM Rankings Are Split Between Prestige and Production Gravity
llm-rankings

LLM Rankings Are Split Between Prestige and Production Gravity

The most useful LLM leaderboard story this week is the boring-looking one: the quality board barely moved, while the usage board kept rearranging itself underneath. That is exactly the kind of split engineers should care about. Benchmarks tell you what wins in a controlled comparison. Production token volume tells you
03 Jul 2026 6 min read
LLM Rankings Are Split Between Prestige and Production Gravity
llm-rankings

LLM Rankings Are Split Between Prestige and Production Gravity

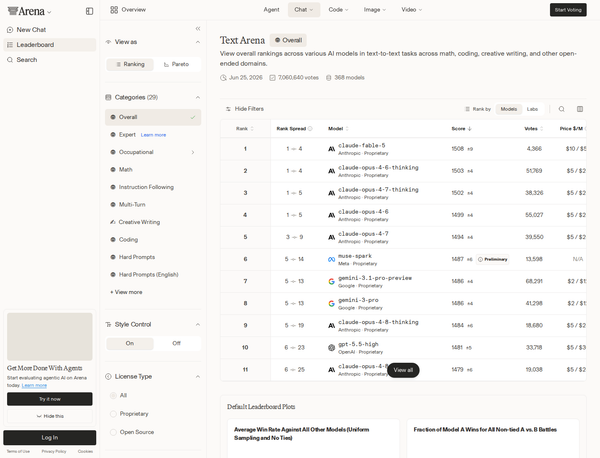
The most useful LLM ranking this week is not the one with the prettiest Elo number. It is the messy one that shows what developers are actually paying to run. Arena's text leaderboard is basically holding still: claude-fable-5 leads at 1508 Elo, followed by claude-opus-4-6-thinking at 1503, claude-opus-4-7-thinking
02 Jul 2026 6 min read
The LLM Leaderboard Is Stable. The Usage Market Is Not.
llm-rankings

The LLM Leaderboard Is Stable. The Usage Market Is Not.

The useful LLM leaderboard story this week is not that a new champion walked onto the stage. It is that the stage barely moved while the loading dock behind it kept rearranging itself. Arena's text leaderboard is stable at the top: Anthropic holds the first five slots with
01 Jul 2026 5 min read
LLM Rankings Have Split Into Two Markets
llm-rankings

LLM Rankings Have Split Into Two Markets

The leaderboard story this week is not that Anthropic is still sitting on the throne. That part is almost boring now. The more useful story is that the market has stopped behaving like there is one throne at all. Arena's Text leaderboard is quiet: claude-fable-5 leads at 1508
29 Jun 2026 5 min read
Claude Still Owns Arena, but the Rankings Now Matter Below the Crown
llm-rankings

Claude Still Owns Arena, but the Rankings Now Matter Below the Crown

The useful story in today's LLM leaderboard is not that Claude is still winning. That has been true long enough to become table stakes. The sharper signal is that the frontier board is turning into a routing map: Anthropic owns the quality-sensitive top end, while a crowded, tightly
27 Jun 2026 5 min read
CodeChat-Eval Measures the Thing Copilots Actually Do: Break Code on Turn Seven
ai-models

CodeChat-Eval Measures the Thing Copilots Actually Do: Break Code on Turn Seven

The most honest coding-assistant benchmark is not the one where a model writes a function and leaves. It is the one where the user comes back nine times asking for small refinements until the code breaks in a way that looks reasonable in the chat and wrong in the test
25 Jun 2026 4 min read
Quantized Reasoning Models May Be Cheaper Per Token and Slower Per Answer
ai-models

Quantized Reasoning Models May Be Cheaper Per Token and Slower Per Answer

The comfortable story about quantization is that smaller weights make inference cheaper. For ordinary generation, that story is often close enough. For reasoning models, it has a missing column: the model may become cheaper per token and more expensive per answer. A new paper on low-bit reasoning models identifies a
25 Jun 2026 4 min read
ToolBench-X Says Your Agent Is Only Good When the Tools Behave
ai-models

ToolBench-X Says Your Agent Is Only Good When the Tools Behave

Function calling benchmarks have spent years grading agents in rooms where the tools behave. ToolBench-X opens the door to the room most teams actually work in: tools drift, fail, wrap fields strangely, disagree with each other, and occasionally make the model look more competent than the system deserves. The new
25 Jun 2026 4 min read
icat-agent Shows the Scaffold Is Now the Product
ai-models

icat-agent Shows the Scaffold Is Now the Product

The interesting part of icat-agent is not that another scaffold moved a SWE-bench number. The interesting part is that it treats the coding agent like a distributed system instead of a long chat transcript with shell access. That is the right abstraction shift, and it is probably where the next
25 Jun 2026 5 min read
Codex Turns AGENTS.md and Environment Context Into Durable Runtime State, Not Prompt Confetti
codex

Codex Turns AGENTS.md and Environment Context Into Durable Runtime State, Not Prompt Confetti

Codex is turning repository instructions and environment context into runtime state instead of treating them like prompt confetti. That is less flashy than a new model picker or a prettier terminal UI, but it is the kind of machinery long-running coding agents need before teams can trust resume, fork, compaction,
25 Jun 2026 5 min read
Codex Routes MCP Auth Through the Executor, Because Tool Credentials Should Not Teleport Across Trust Boundaries
codex

Codex Routes MCP Auth Through the Executor, Because Tool Credentials Should Not Teleport Across Trust Boundaries

Codex’s latest MCP work is not glamorous, but it is the kind of change that decides whether coding agents become usable infrastructure or just very confident browser tabs with shell access. The headline is OAuth for executor-routed HTTP MCP servers. The actual story is sharper: OpenAI is making tool
25 Jun 2026 5 min read
← Newer Posts Page 7 of 141 Older Posts →
The LGTM © 2026
  • Sign up
Powered by Ghost